Medicine × LLM × R
Keynote · R Conference Malaysia 2026, Sunway University
Department of Biostatistics & Research Methodology, Universiti Sains Malaysia
wnarifin.github.io
21 November 2026
Outlines
Medicine and computers: from computer-aided diagnosis to AI
The rise of large language models (LLMs) and what they do for medicine
Where stands: packages and showcases
Take-home messages
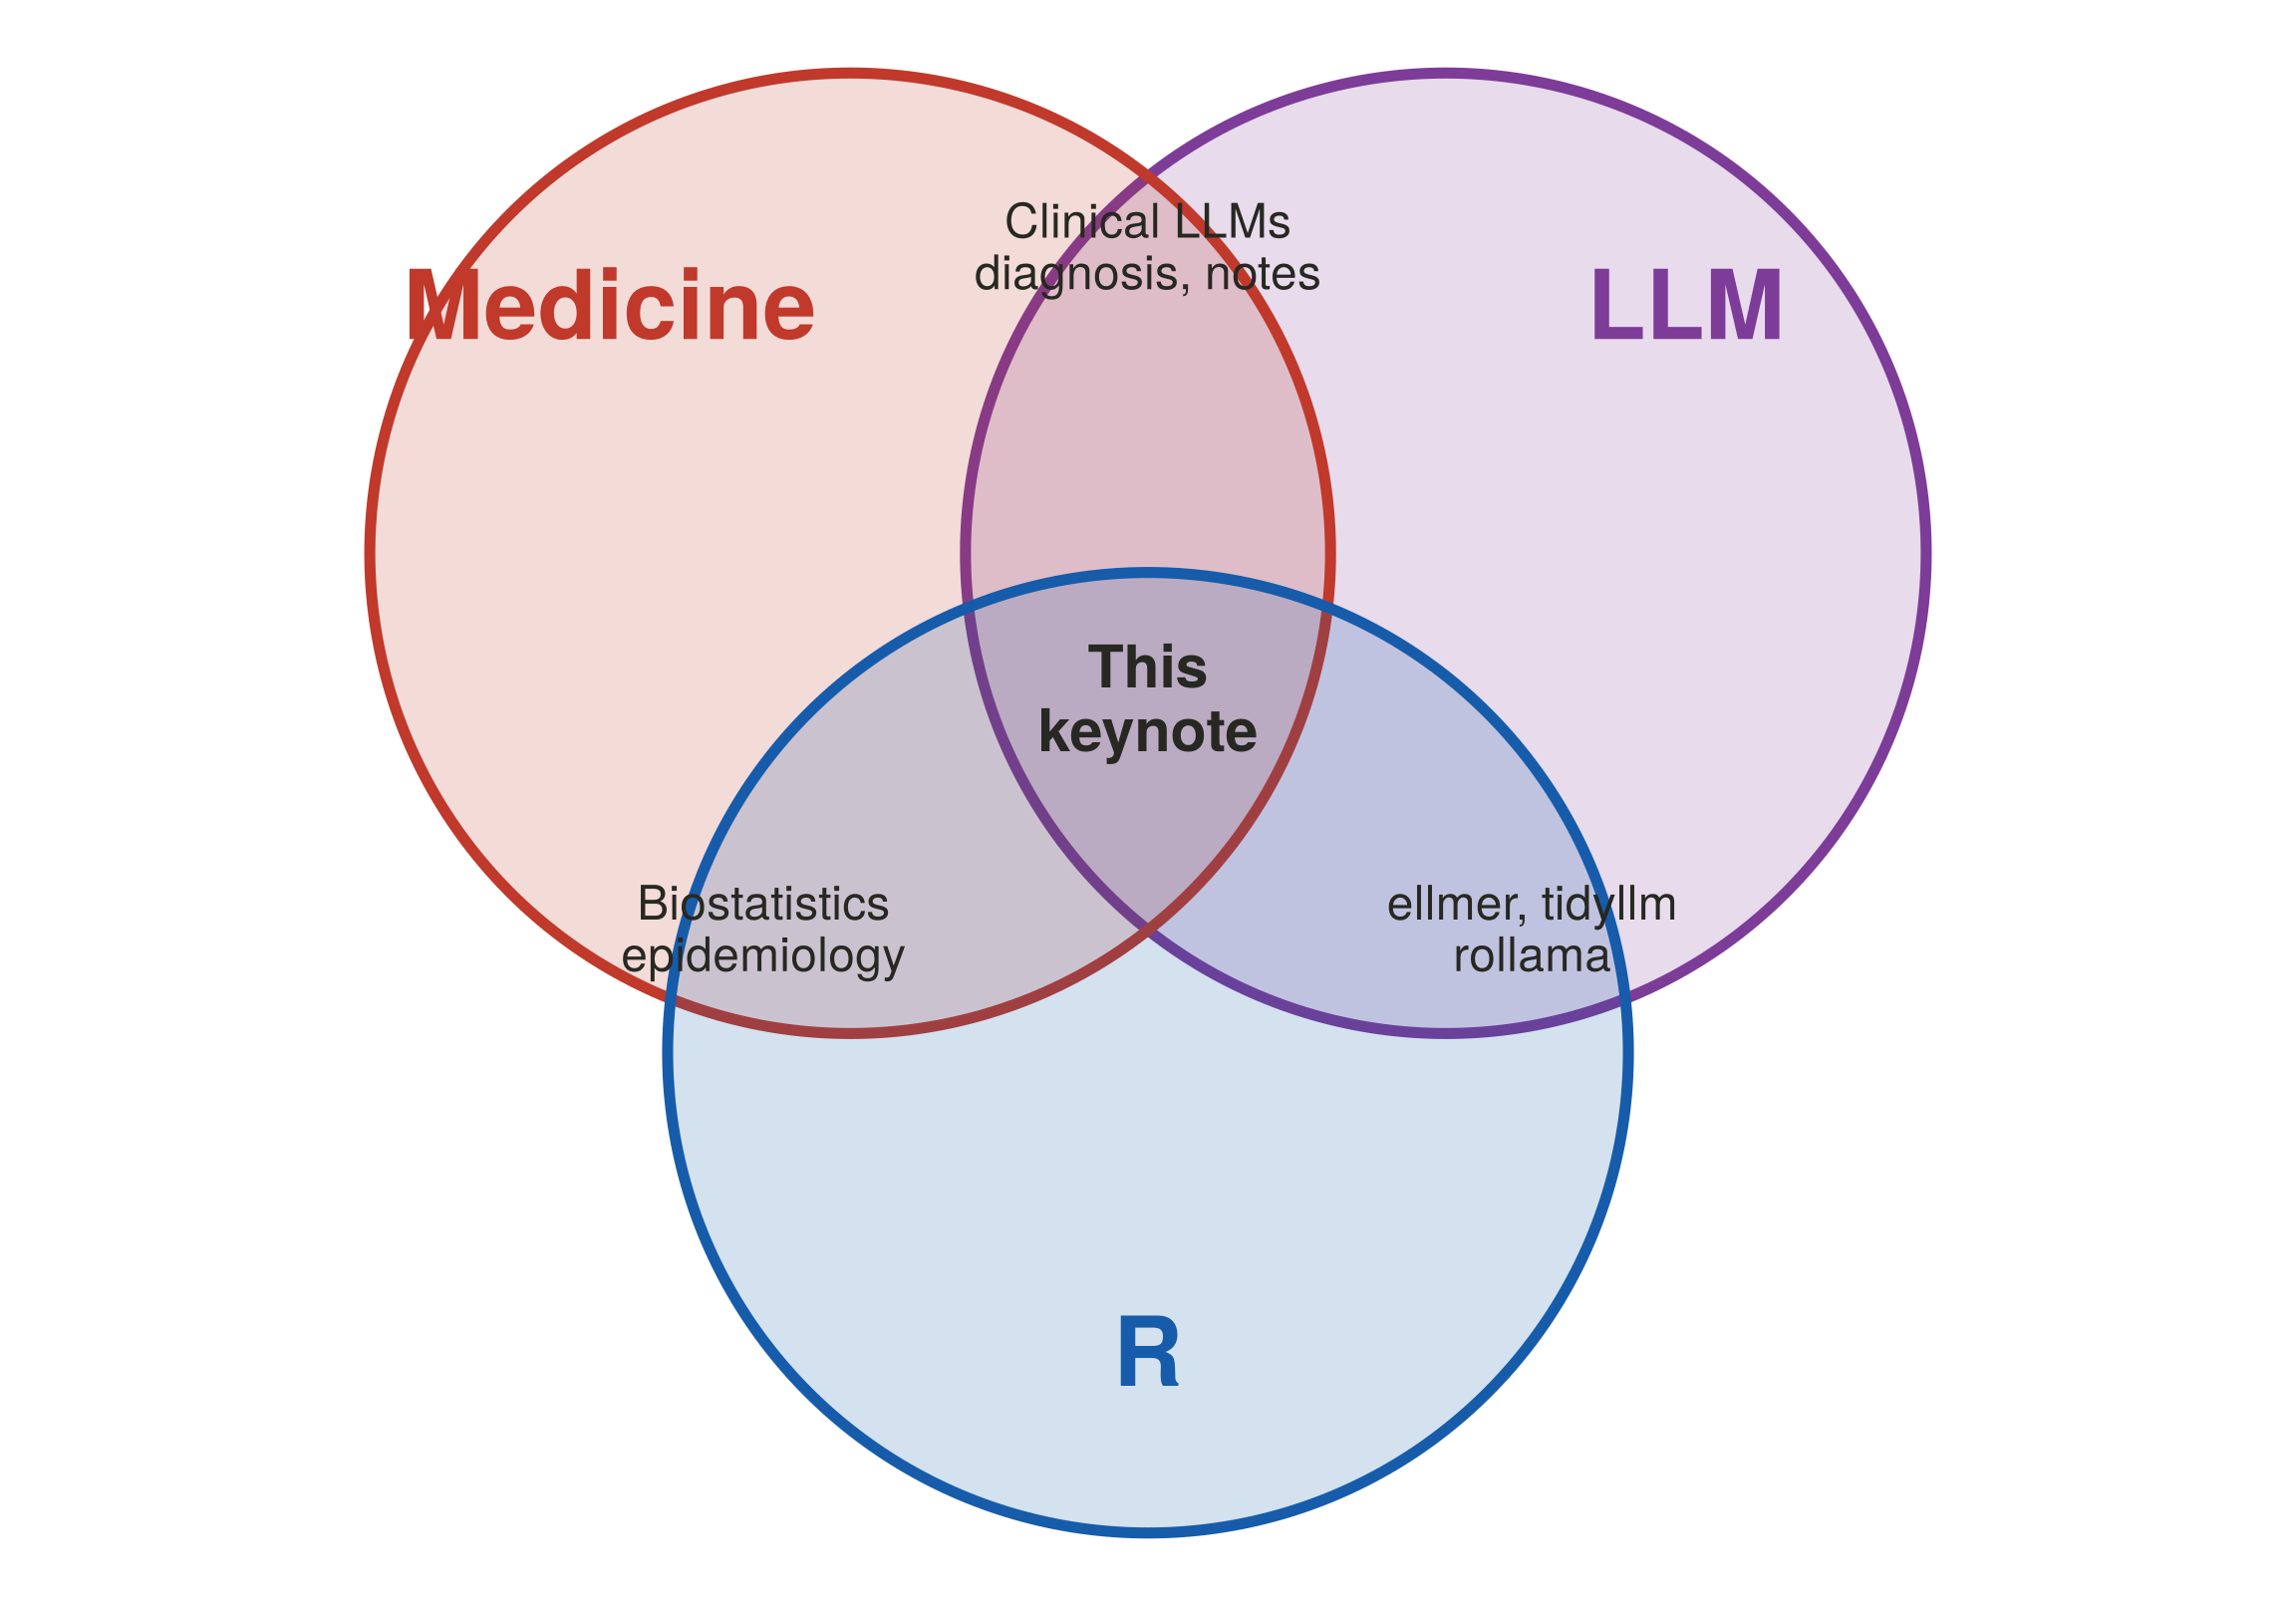
Medicine × LLM ×
Part 1
Medicine and computers: from computer-aided diagnosis to AI
Medical tasks that call for computer assistance
Diagnosis
Differential diagnosis, probabilistic reasoning (Ledley and Lusted 1959; de Dombal et al. 1972)
Medical imaging
Detection and classification in radiology, retina, skin (Doi 2007; Gulshan et al. 2016)
Decision support
Alerts, order checking, guideline reminders (Bates et al. 1998; Kawamoto et al. 2005)
Prediction
Risk scores and early warning, e.g. sepsis (Wong et al. 2021)
Documentation
Records, notes, discharge summaries: a major source of clinician burden
Evidence synthesis
Searching, screening and extracting data from studies (Gartlehner et al. 2024)
Discovery
Protein structure, drug targets (Jumper et al. 2021)
Research & education
Statistical analysis, teaching, assessment
Common thread: large volume, complex reasoning, repetitive work, where humans tire and err.
From computer-aided diagnosis to AI: a timeline
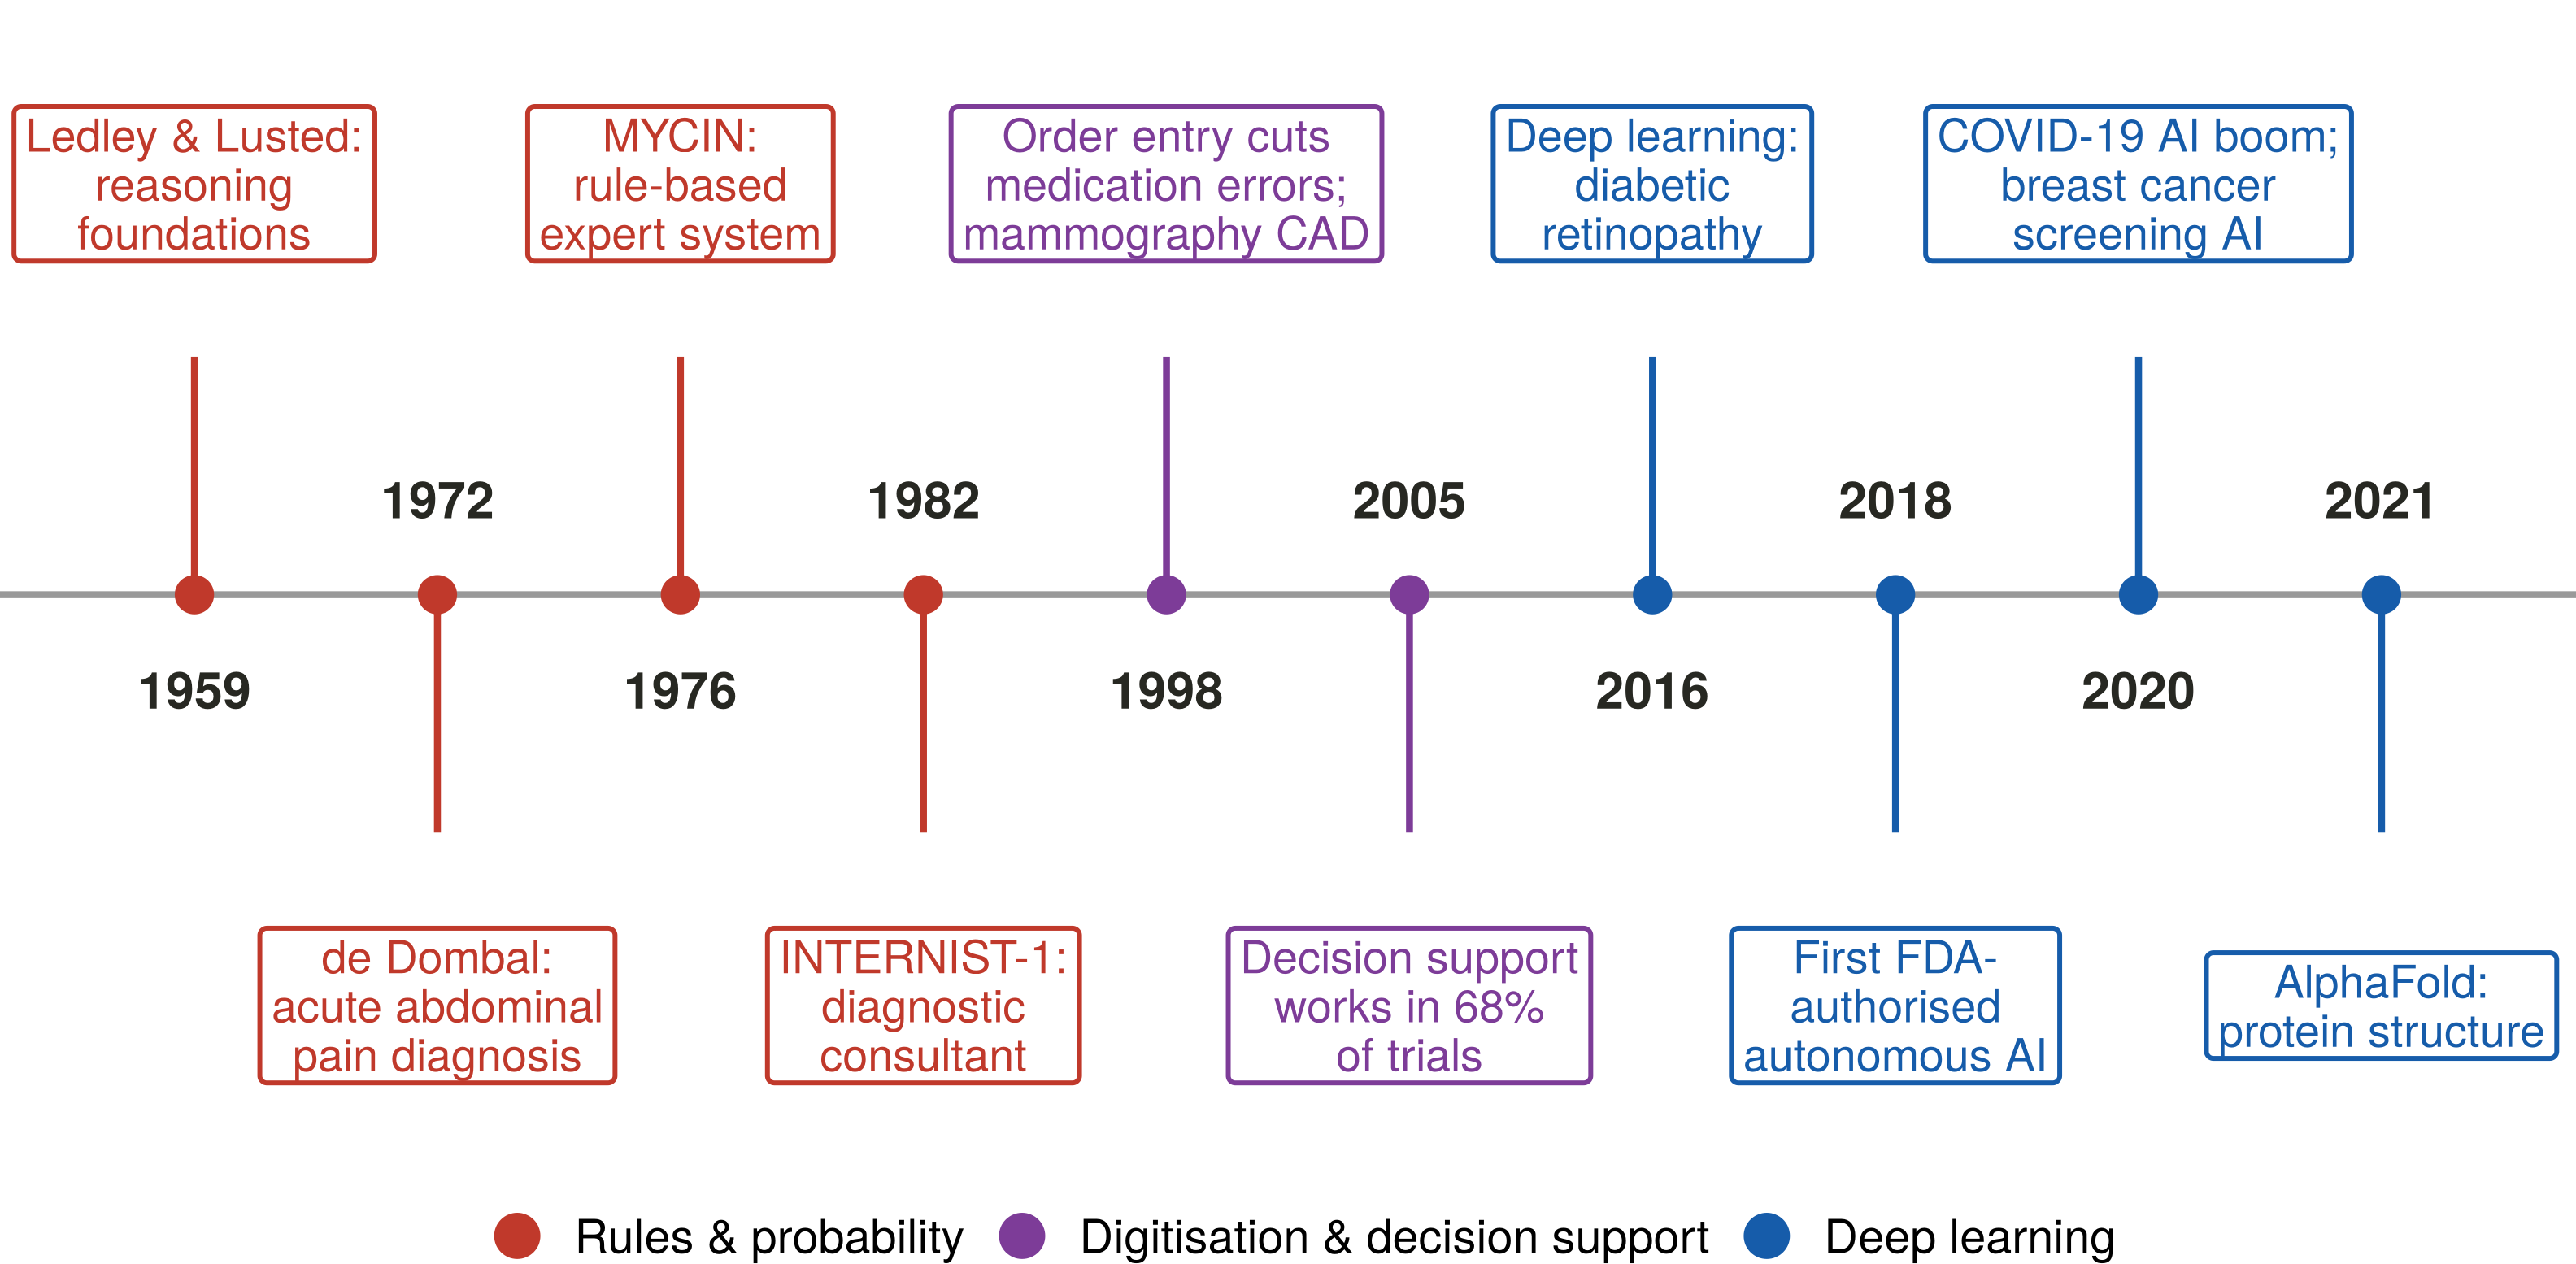
Era 1: rules and probabilities (1959–1980s)
- Ledley and Lusted (1959): diagnosis as symbolic logic + probability (Bayes) + value theory
- de Dombal et al. (1972): prospective real-time comparison in 304 patients with acute abdominal pain
- Computer accuracy 91.8% vs most senior clinician 79.6%
- MYCIN (Shortliffe 1976): if–then rules for infections and antibiotic choice
- INTERNIST-1 (Miller, Pople, and Myers 1982): diagnostic consultant for general internal medicine
Bayes’ theorem was the first “AI” at the bedside
Knowledge was hand-coded by experts (expert system): powerful but brittle and hard to maintain
Era 2: digitisation and decision support (1990s–2000s)
Clinical decision support
- Computerised physician order entry: nonintercepted serious medication errors ↓ 55% (Bates et al. 1998)
- Systematic review of 70 RCTs: decision support improved practice in 68% of trials; best when automatic and within workflow (Kawamoto et al. 2005)
CAD in imaging
- Mammography CAD approved by FDA in 1998 (Doi 2007)
- But in real-world use, sensitivity ↑ (not sig.), specificity ↓, and biopsy rate ↑ 19.7%; increased potential harms of screening mammography with uncertain clinical benefit (Fenton et al. 2007)
Lesson: workflow fit and real-world evaluation decide success
Era 3: deep learning (2012–today)
- Retina: diabetic retinopathy, AUC 0.99 (Gulshan et al. 2016)
- Skin: CNN on par with 21 dermatologists (Esteva et al. 2017)
- First autonomous AI authorised by FDA: sensitivity 87.2%, specificity 90.7% (Abràmoff et al. 2018)
- Breast screening: fewer false positives and negatives than radiologists (McKinney et al. 2020)
- COVID-19: chest CT + clinical data, AUC 0.92 (Mei et al. 2020)
- AlphaFold: protein structure prediction (Jumper et al. 2021)
A cautionary tale
A widely implemented proprietary sepsis model: AUC 0.63 on external validation, missed 67% of sepsis cases, but alerts for 18% of all inpatients – alert fatigue (Wong et al. 2021)
2020: the COVID-19 AI boom … and its lessons
The promise
- Urgent need: RT-PCR took up to 2 days and test kits were short (Mei et al. 2020)
- AI on chest CT and X-ray looked like a fast answer
- Within months: hundreds of diagnostic and prognostic models
The reality
- Systematic review of 731 prediction models: “Most published prediction model studies were poorly reported and at high risk of bias such that their reported predictive performances are probably optimistic” (Wynants et al. 2020)
- Systematic review of 62 studies on machine learning for COVID-19 imaging: none “… are of potential clinical use due to methodological flaws and/or underlying biases” (Roberts et al. 2021)
Speed without methodology gives models that cannot be used
Lessons from 60 years of computers in medicine
- Computers are assistants: they extend, not replace, clinicians
- Workflow integration matters as much as accuracy
- Evaluation in real-world settings is non-negotiable: sensitivity, specificity, calibration, impact
- Most of the remaining burden is text: notes, letters, reports, papers
… and text is exactly what large language models are good at
Part 2
The rise of large language models
From “Attention is all you need” to today
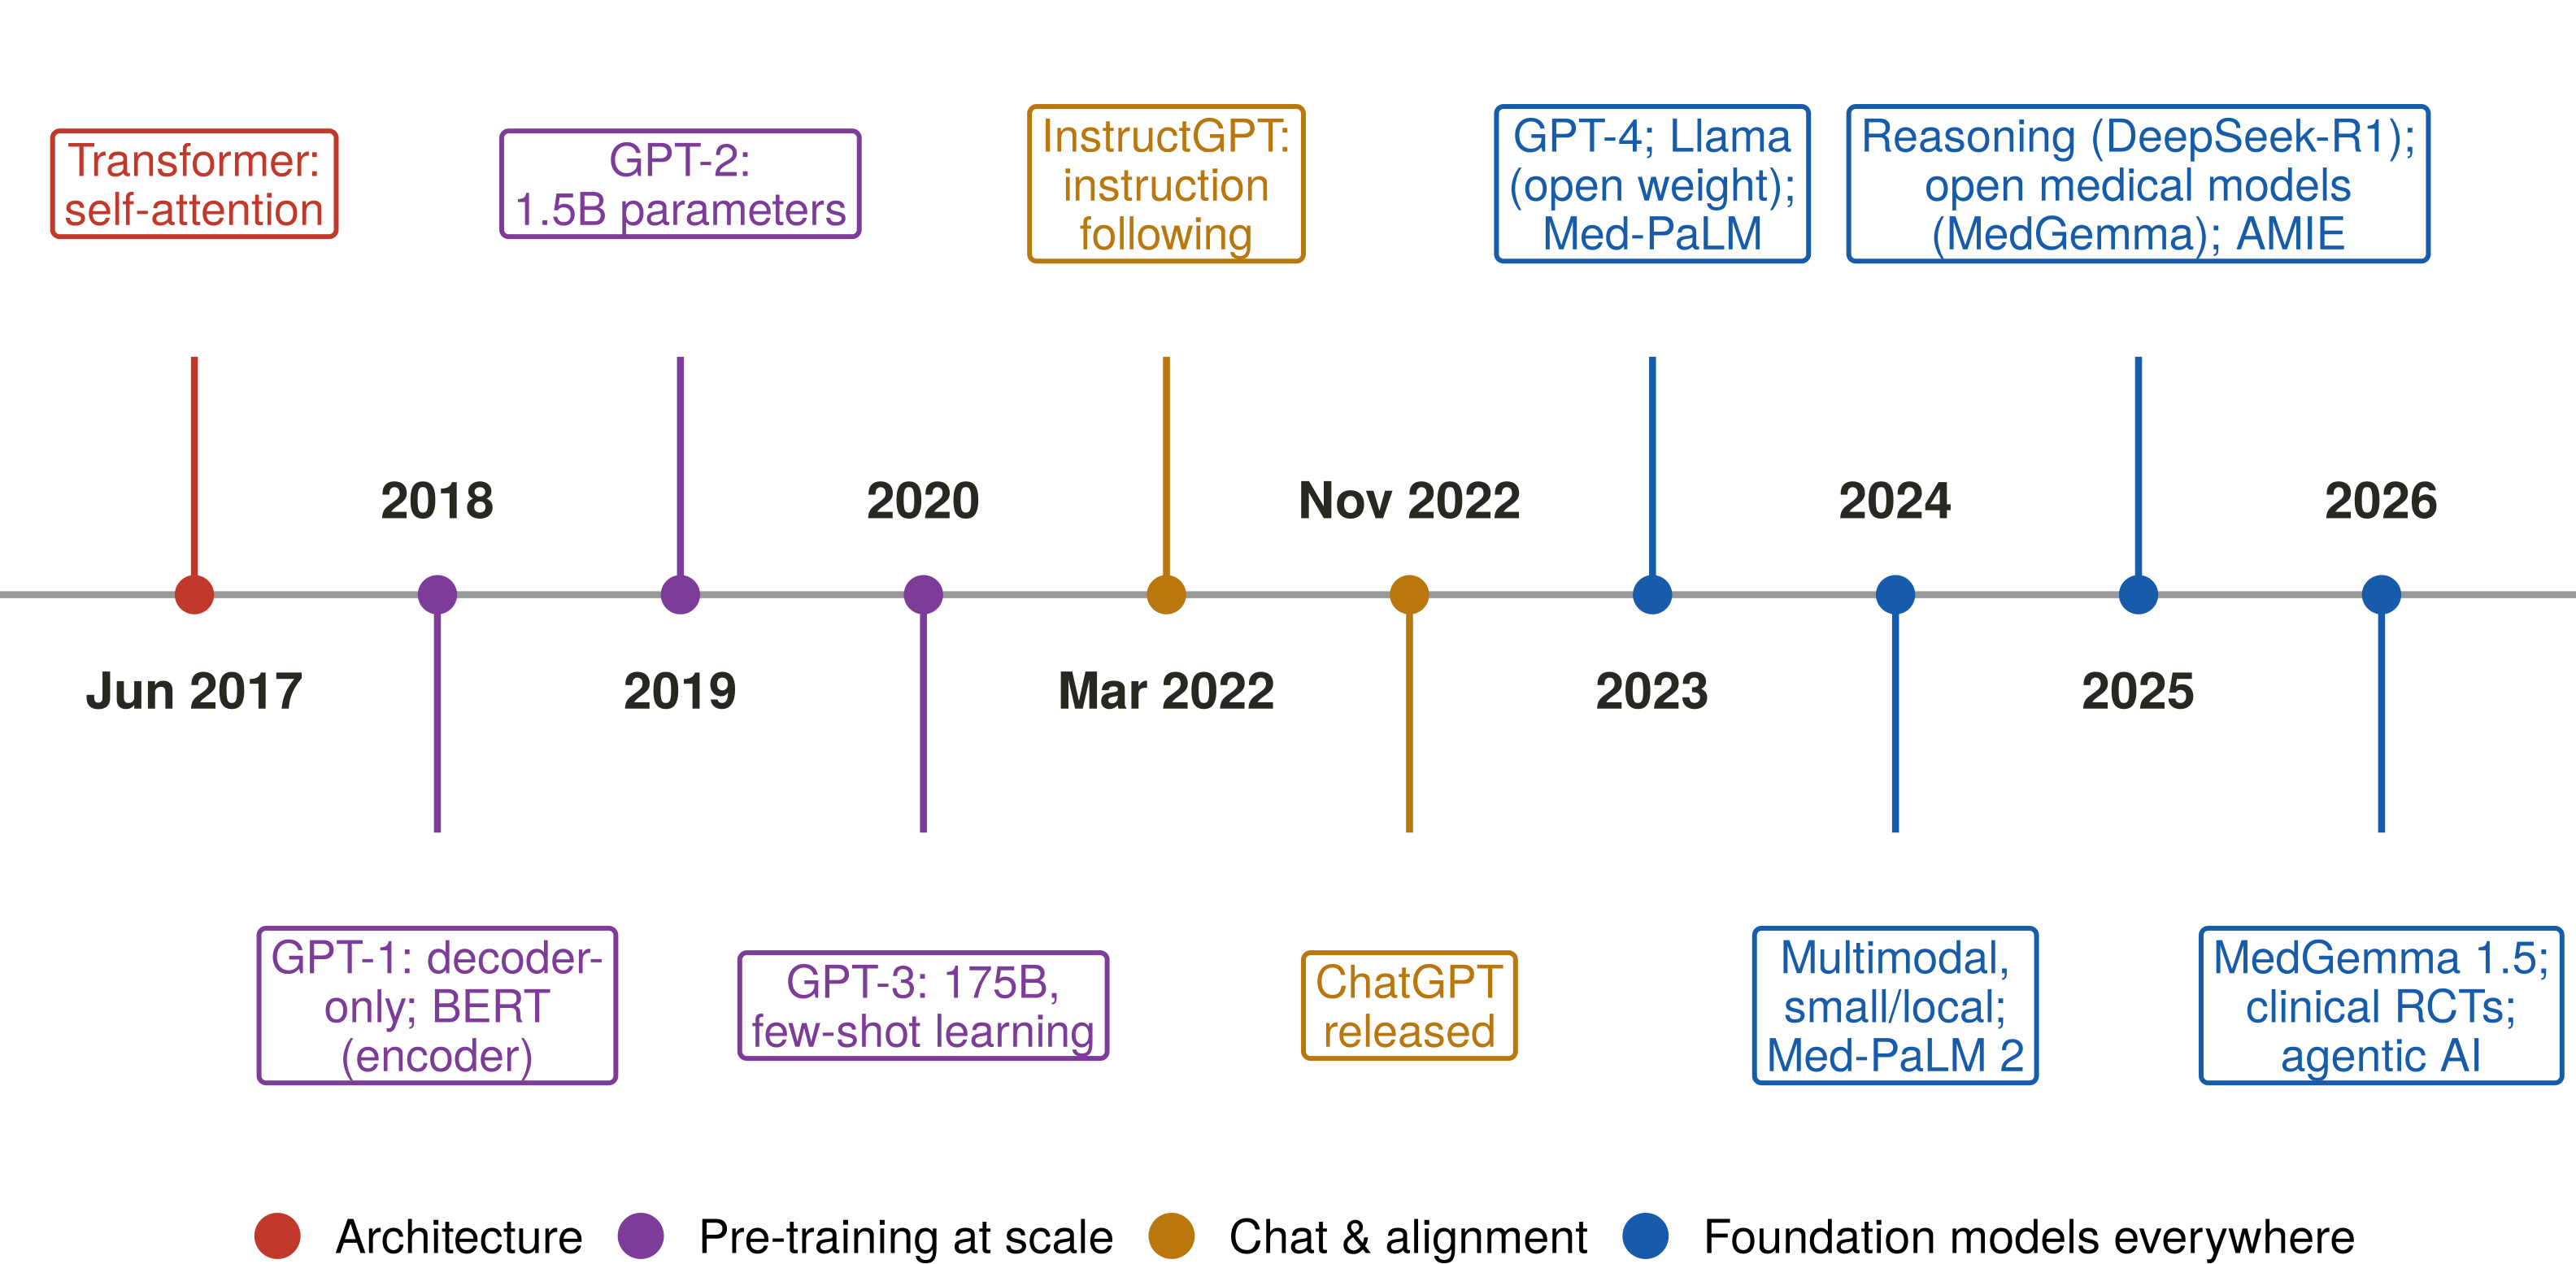
Vaswani et al. (2017); Radford et al. (2018); Devlin et al. (2019); Radford et al. (2019); Brown et al. (2020); Ouyang et al. (2022); OpenAI (2022); OpenAI (2023); Touvron et al. (2023); Singhal et al. (2023); Singhal et al. (2025); Guo et al. (2025); Sellergren et al. (2025); Google Research and Google DeepMind (2026); McDuff et al. (2025); O’Sullivan et al. (2026)
Early signals: LLMs know (a lot of) medicine
Medical exams
- ChatGPT at or near the passing threshold on all three USMLE steps, without specialised training (Kung et al. 2023)
- Med-PaLM: 67.6% on MedQA (Singhal et al. 2023) → Med-PaLM 2: 86.5% (Singhal et al. 2025)
Communication with patients
- 195 patient questions from a public forum: evaluators preferred chatbot responses to physician responses in 78.6% evaluations – better quality, more empathic than human physicians (Ayers et al. 2023)
But …
Of 519 LLM evaluation studies (2022–2024), only 5% used real patient-care data (Bedi et al. 2025). So, is it valid?
How medicine benefits from LLMs: by task
| Task | Example study | Key finding |
|---|---|---|
| Diagnosis | AMIE, 302 differential diagnoses of complex cases (McDuff et al. 2025) | Top-10 accuracy: AMIE alone 59.1% vs unassisted clinicians 33.6% |
| Physician RCT (Goh et al. 2024) | LLM access did not improve physicians’ diagnostic reasoning; but the LLM alone scored 16 percentage points higher than physicians with conventional resources | |
| Cardiology RCT (O’Sullivan et al. 2026) | Fewer clinical errors with AMIE assistance (13.1% vs 24.3%) | |
| Documentation | Ambient AI scribes, RCTs (Lukac et al. 2025; Afshar et al. 2025) | Less time in notes, less work exhaustion; occasional inaccuracies |
| Summarisation | 4 clinical summarisation tasks (Van Veen et al. 2024) | LLM summaries were superior to medical experts’ in 36% of cases (equivalent in 45%) |
| Information extraction | 1026 lung cancer, 191 pediatric osteosarcoma pathology reports (Huang et al. 2024) | classification accuracy: 89% and 98.6% respectively |
| Evidence synthesis | Data extraction from RCTs for systematic review (Gartlehner et al. 2024) | 96.3% accuracy over 160 data elements from 10 papers |
| Dialogue / history-taking | Conversational AMIE (Tu et al. 2025) | Higher diagnostic accuracy than primary care physicians in text-based consultations |
Human + AI collaboration
- RCT of 70 clinicians: AI as first or second opinion improved diagnostic accuracy (85% and 82% vs 75% with conventional resources) – complementary role of AI (Everett et al. 2026)
- Just giving clinicians a chatbot was not enough – emphasis on AI as assistant (Goh et al. 2024)
An LLM is an assistant, not a replacement
Risks we must manage
- Hallucination: fluent but fabricated content (Wang and Zhang 2024; Thirunavukarasu et al. 2023)
- Bias: gender-, race-biased responses (Wang and Zhang 2024; Omiye et al. 2023)
- Inconsistency: different answers to the same question (Omiye et al. 2023)
- Privacy: patient data sent to cloud providers
- Changing models: behaviour shifts between versions, opaque training data (Iozzia 2026)
- Evaluation gap: few studies on real patient data (Bedi et al. 2025)
These are statistical and governance problems, not only engineering ones
Part 3
Where stands
Python dominates LLM development
- Pre-training, fine-tuning and serving: PyTorch, Hugging Face Transformers, vLLM, …
- In 2024, Python overtook JavaScript as the most used language on GitHub, driven by AI and data science (GitHub 2024)
- Practitioner LLM books assume Python and PyTorch skills, e.g. Iozzia (2026)
So… is still relevant for LLMs in medicine?
Most medical users do not build LLMs; they use them
Build the engine
- Pre-training from scratch
- Fine-tuning, quantisation
- Serving at scale
Drive the car
- Inference: prompt a model via API or locally
- Structure text into analysable data
- Evaluate the outputs statistically
- Report and share: Quarto, Shiny
For the second column, is a first-class citizen
Where stands
1. Inference
Cloud APIs (OpenAI, Claude, Gemini, …) and local models via Ollama: same R session, one interface (Wickham et al. 2026; Gruber and Weber 2025)
2. Prototyping research ideas
Test an idea in minutes, next to your data, your models and your plots
3. Text → data
Extract structured variables from notes and papers straight into data frames (Brüll 2026; Arifin 2026b)
4. Evaluation
Accuracy, agreement, CIs, trials of LLM tools: biostatistics’ home turf (Couch 2025d)
5. Simple apps
Shiny + chat UI for patient education or data Q&A in a few lines (Cheng, Sievert, and Aden-Buie 2026)
6. Reproducible reporting
Prompts, model versions, seeds and results in one Quarto document
7. Privacy-first local LLMs
Patient data stay on your machine with Ollama + R (Arifin 2026a)
8. Trusted in clinical research
R-based submission packages reviewed by the FDA (R Consortium 2024)
9. RAG, tools & agents
Retrieval over guidelines, tool calling, MCP: R functions as tools (Kalinowski and Falbel 2026; Couch 2025c)
The + LLM package landscape
| Purpose | Packages |
|---|---|
| Unified chat interface (cloud + local) | ellmer (Wickham et al. 2026), tidyllm (Brüll 2026) |
| Local models via Ollama | rollama (Gruber and Weber 2025), ollamar (Lin and Safi 2025) |
| LLM over data frame columns | mall (Ruiz 2025b) |
| Retrieval-augmented generation | ragnar (Kalinowski and Falbel 2026), rchroma |
| Evaluation | vitals (Couch 2025d) |
| Apps | shinychat (Cheng, Sievert, and Aden-Buie 2026), querychat (natural language → SQL over data) |
| Coding assistants | btw (Aden-Buie, Couch, and Cheng 2026), gander (Couch 2025b), chores (Couch 2025a), chattr (Ruiz 2025a), gptstudio (Nivard, Wade, and Calderon 2025) |
| Model Context Protocol | mcptools (Couch 2025c): let assistants use your R session, and R use MCP tools |
| Vision | kuzco (computer vision with LLMs) (Hull 2025) |
Today’s showcase: rollama → tidyllm → ellmer, from basic to more advanced
Showcase: tasks from Parts 1 & 2, done in
| # | Medical task (Parts 1 & 2) | Package | What we do |
|---|---|---|---|
| 1 | Patient communication, translation | rollama |
Explain a finding in simple Malay, locally |
| 2 | Triage / text classification | rollama |
Zero-shot classification of complaints |
| 3 | Information extraction | tidyllm |
Structure clinical notes into a data frame |
| 4 | Extraction + evaluation | ellmer |
Extract labs from many notes, check against gold standard |
| 5 | Decision support (calculation) | ellmer |
Tool calling: R computes eGFR, the LLM explains |
| 6 | Patient education, grounded in a document | ragnar |
Retrieval (RAG) over a Malay Wikipedia page |
| 7 | Simple app | ellmer + shinychat + ragnar |
Patient-education chatbot that cites the page |
All examples use open-weight models through Ollama on a local PC, except where noted. Full code and output: demo document (next slides).
Showcase
rollama · tidyllm · ellmer · ragnar · shinychat
Showcase: demo document
rollama: basic local inferencerollama: zero-shot triage classificationtidyllm: structuring clinical notesellmer: extraction at scale, then evaluationellmer: tool calling (eGFR in )ragnar: grounding answers in a document (RAG)ellmer+shinychat+ragnar: a patient-education app
Practical considerations
Privacy & ethics
- Identifiable patient data → local models or approved, contracted services only
- Ethics approval and data governance as for any data processing
Reproducibility
- Record model name + version, prompts,
seed,temperature - Keep prompts and code in Quarto / Git
Validation
- Gold standard on a sample; report accuracy with CIs, agreement, errors by type
- Re-validate when the model changes
Resources
- Local: gaming-grade GPU for 3–14B models
- Cloud: cost per token, rate limits, downtime
Learn more
Exploring Large Language Models With
wnarifin.github.io/explore_llm_with_r (Arifin 2026a)
- Local LLMs, text generation, vision
- Embeddings, classification
- RAG, tool calling and agents
- Fine-tuning and “LLM from scratch” (in progress)
Workshop materials
Structuring clinical notes with and LLMs: wnarifin.github.io/workshop.html (Arifin 2026b)
Package documentation
This talk’s code
Take-home messages
- Computers have assisted medicine for 60+ years; LLMs are the newest assistant, and they speak text
- LLMs already help with diagnosis, documentation, summarisation and extraction, but evaluation on real data lags behind
- Python builds the models; is highly relevant for using them in medicine: inference, prototyping, text → data, evaluation, apps, reporting
- Start with
rollama(local), structure data withtidyllm, grow withellmerandragnar - Our biostatistics strengths, validation, reproducibility, inference, are exactly what medical LLM work needs
Medicine × LLM × : the centre of the Venn diagram is ours to build
References
Thank you!
Dr. Wan Nor Arifin
wnarifin@usm.my · wnarifin.github.io
Slides: wnarifin.github.io/2026-r-conf
Dr. Wan Nor ArifinR Conference Malaysia 2026Medicine × LLM × R